Day 472: Spreadsheets & Browserflow
This post is for thinking through Browserflow’s system design when it comes to interfacing with spreadsheets. (This is a warning that this post is BOOOOOORIIINNNNNGGG so come back another day unless you’re interested in getting into the weeds of browser automation.)
Romain (a great supporter and mentor for Browserflow) recently shared this flow he made for following the makers of the top products of the day from Product Hunt: https://browserflow.app/shared/f8949c5a-0af4-4e93-b50a-1ca43be38514
Here’s how it works at a high level
For each top product of the day, it opens the product page in a new tab
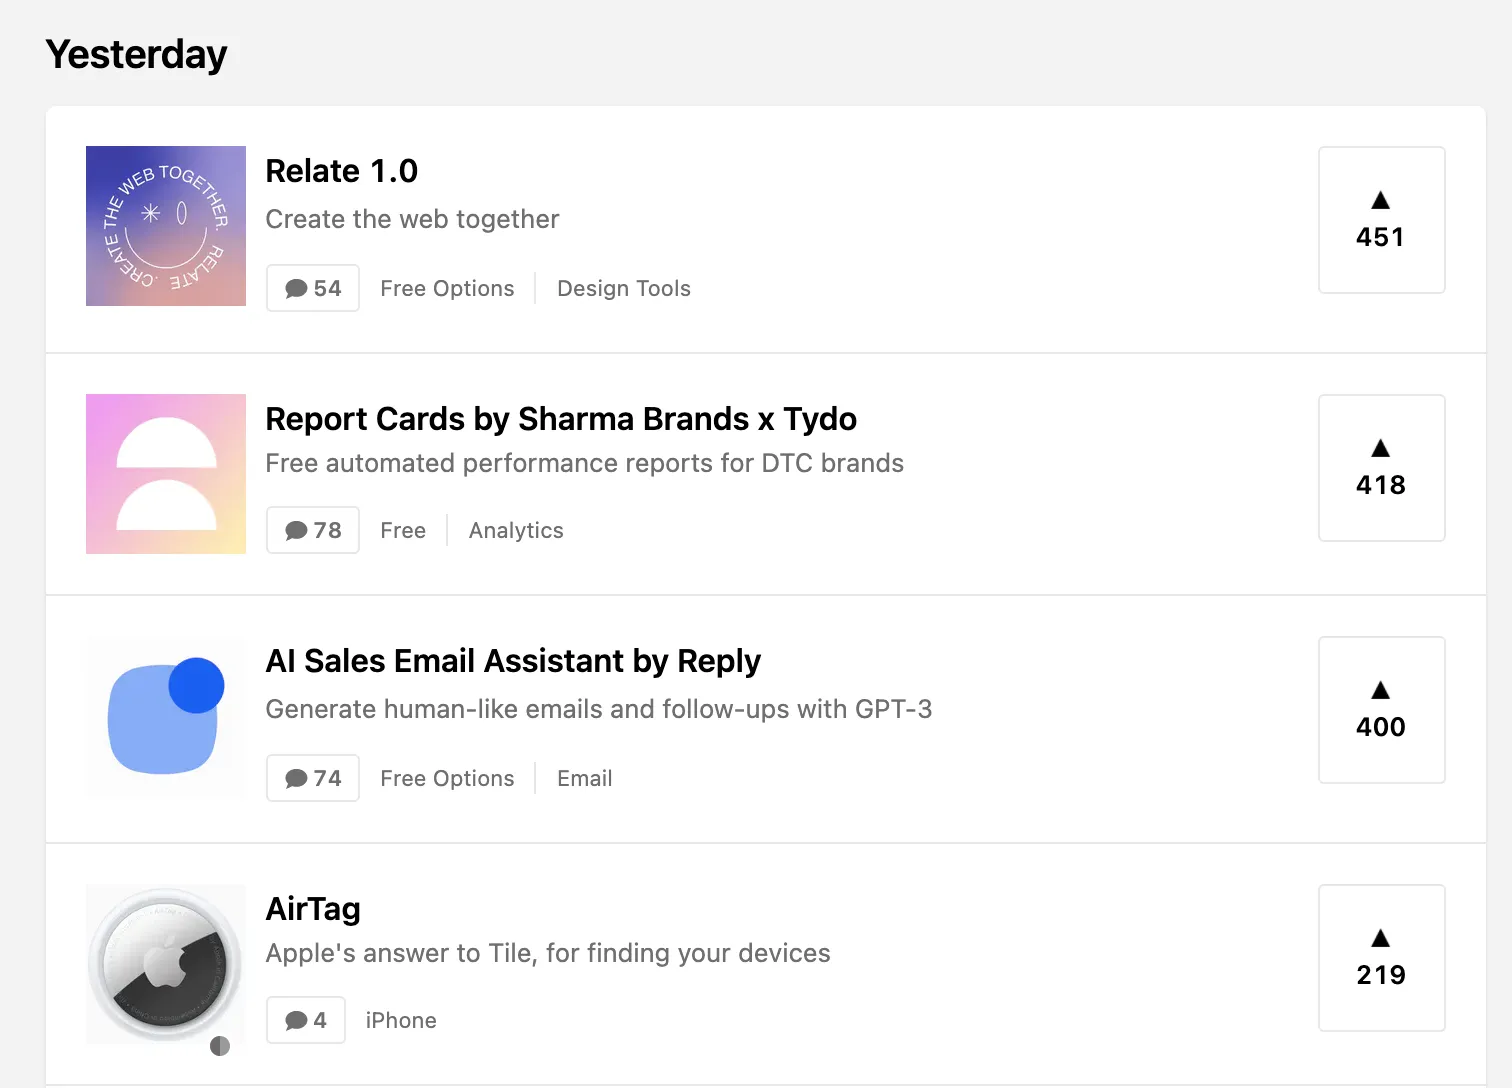
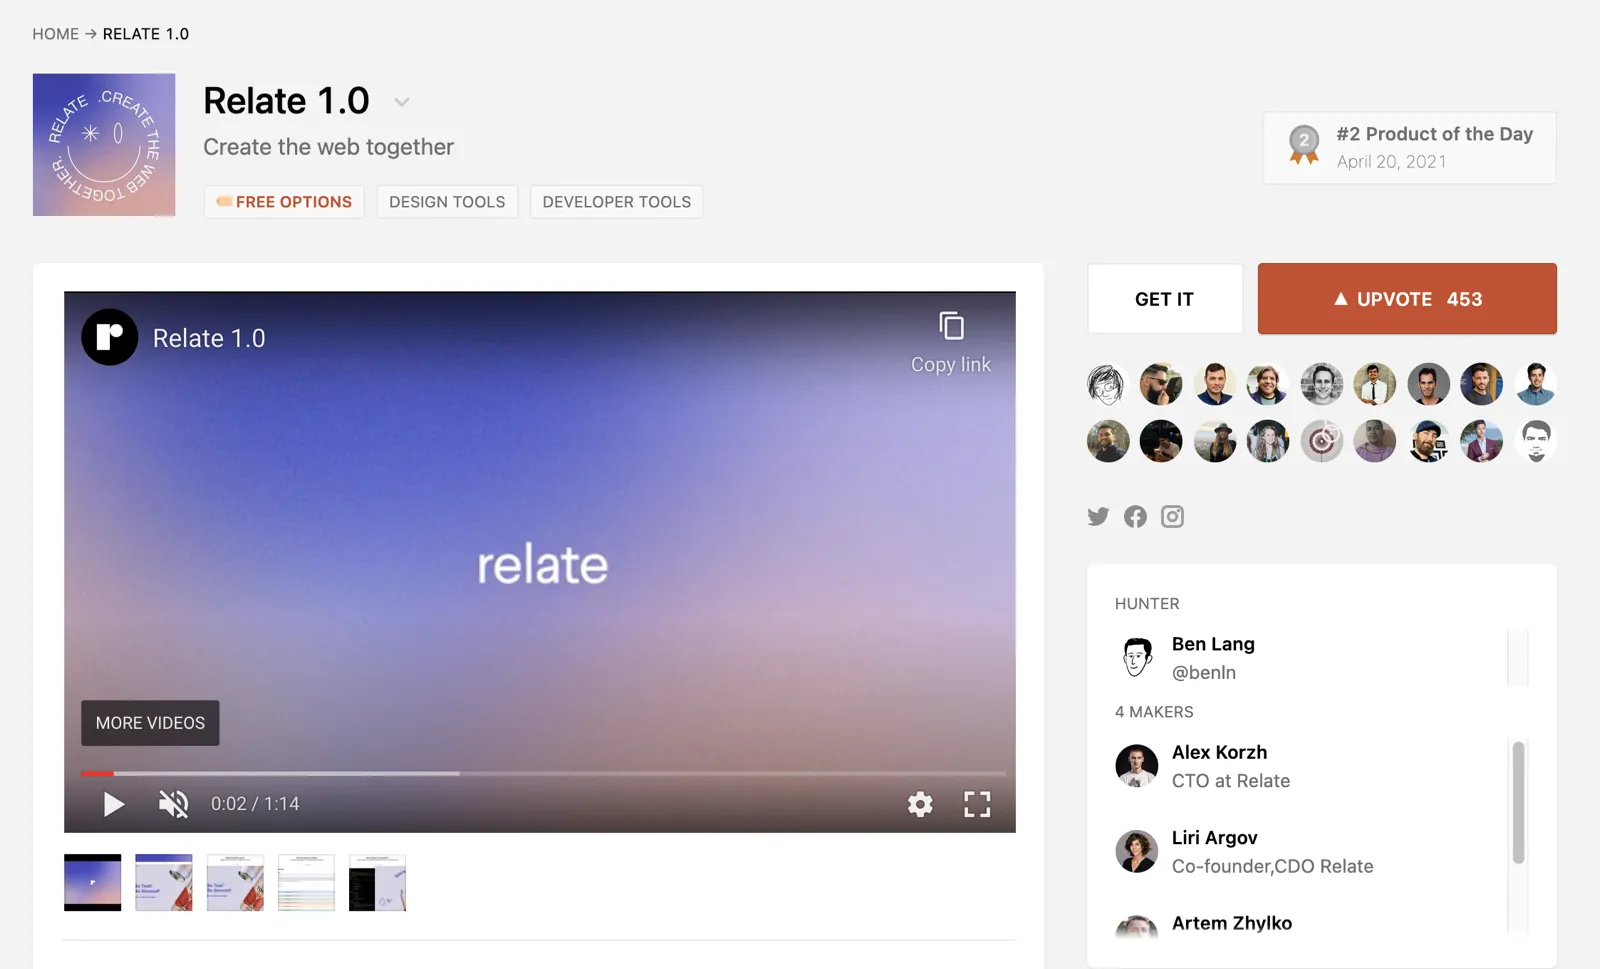
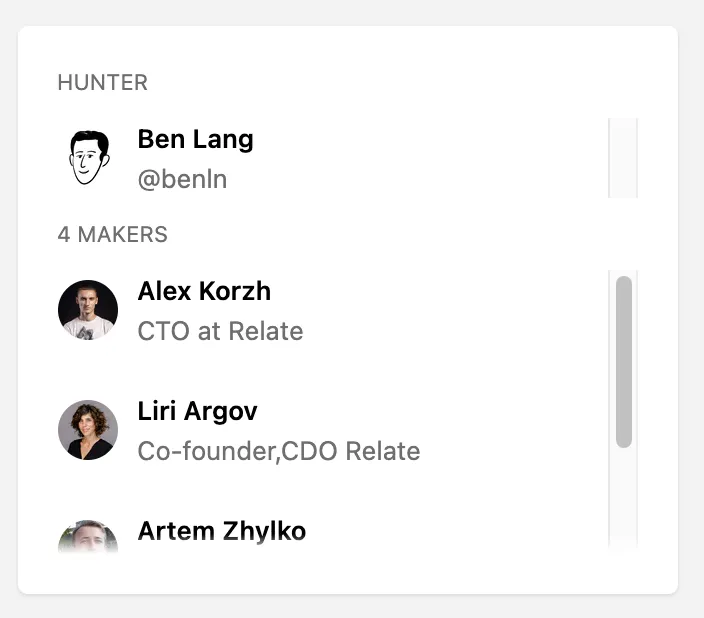
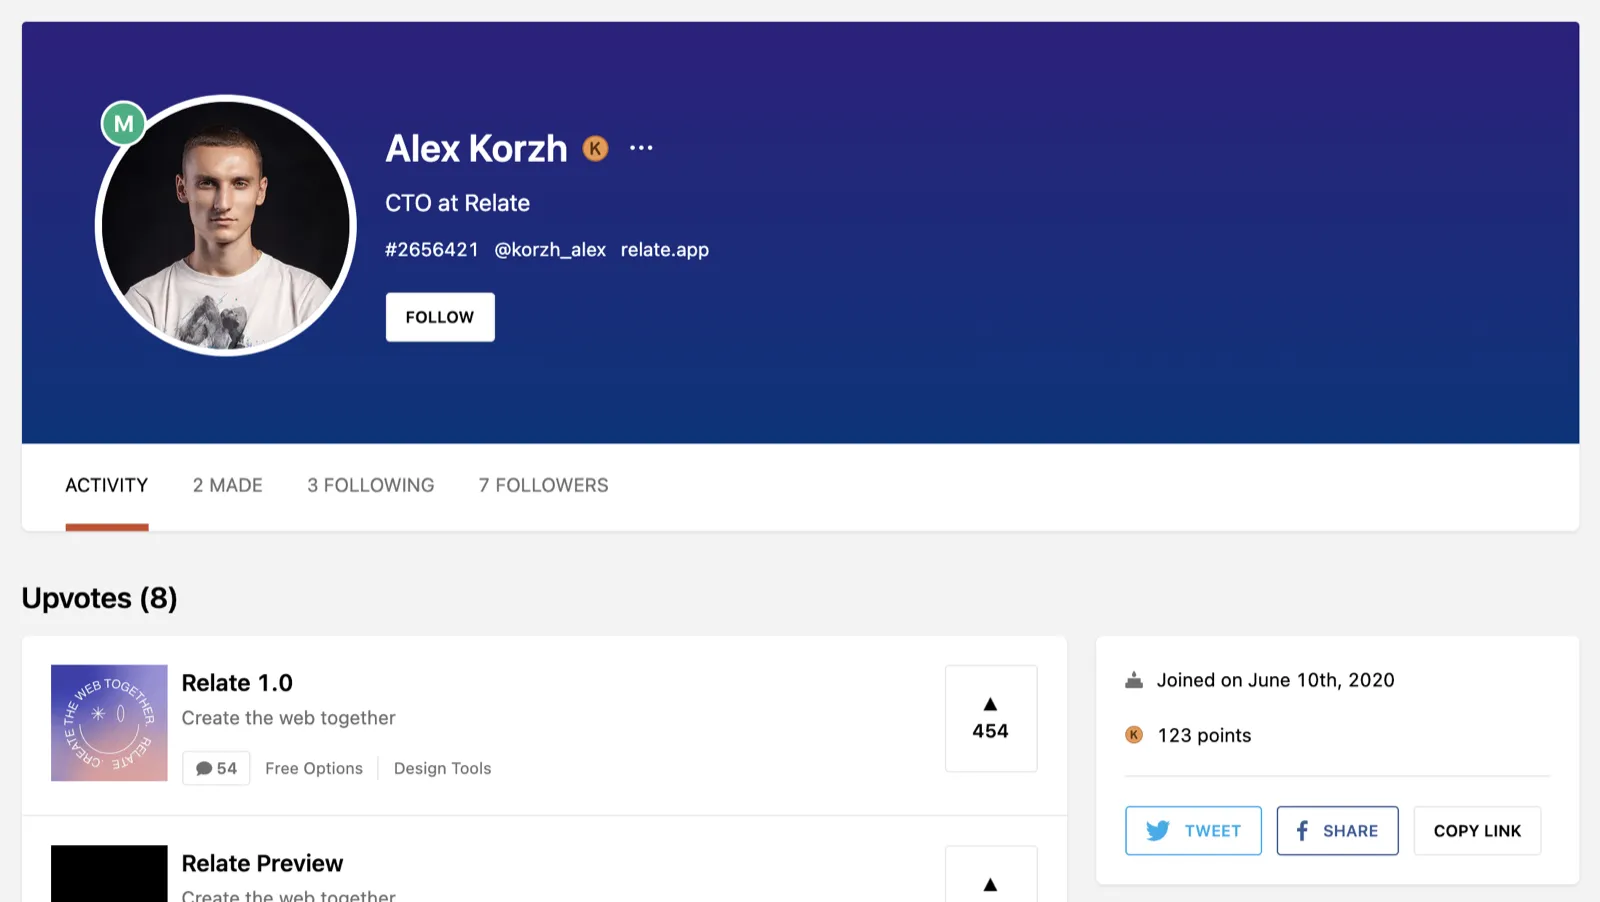
For each maker of the product, it opens their maker page in a new tab and clicks the follow button
This flow is great for understanding the areas where Browserflow can improve because while the details differ between flows, the overall structure of this flow is present in many of the workflows that people want to automate.
In essence, it boils down to: Go through a list of items and do something for every item in that list.
The ProductHunt case is a bit more involved since it has two layers of lists (a list of products and a list of makers for each product), but the core structure is the same.
Persisting State
So how well does Browserflow handle this type of flow?
If the flow is built correctly and handles all edge cases properly, Browserflow would work perfectly. It will go through and automate everything you want it to.
But of course, it’s never that simple. There are always edge cases, and if you run into one without handling it, Browserflow won’t know what to do and would stop the flow. Using the ProductHunt example, you might have flow humming along perfectly fine before running into this page:
This page would break the flow because there are no makers listed for the product. This can be solved by first checking to see if there are makers for the product before trying to loop through them. But what if you’ve already processed a bunch of products and makers before encountering this edge case?
Too bad — you’ll have to process them all over again. When you run a flow, it’s run from a blank state without knowledge of what happened in previous flows. So restarting the flow would mean starting from the very first product and re-doing the automation all over again.
For small lists, this isn’t much of an issue. But if you run into an error after already having processed hundreds of items, it’s a huge waste of time because you’re repeating work you’ve already done.
So how can we have flows remember what they’ve already done and skip those parts?
Spreadsheets to the rescue!
Every time Browserflow successfully follows the makers of a product, it can write the product to a spreadsheet that it can later reference so that it will skip them in the future. The spreadsheet can be used as the source of truth for knowing what’s been done and what’s left to be done.
Multi-flow automations
How might this work? One way is to write each product URL to the output spreadsheet when Browserflow is done processing the makers for each product.
This is a fine solution in the case where there aren’t that many products to process, but it becomes unwieldy if you’re working through a huge list that spans many pages because every time the flow is run, you’d need to loop through all the items you’ve already processed in order to get to the ones you haven’t. Is there a way to avoid that?
A solution would be to split up the flow into multiple parts. Currently, the flow is responsible for opening each product page, then opening each maker, then clicking the follow button. Let’s call this the single-flow approach.
A multi-flow approach would separate these parts:
- One flow to collect all the product URLs
- One flow to collect all the maker profile URLs
- One flow to follow each maker
Instead of opening up new tabs in order to process a different kind of page, a flow would concern itself with only one page and create intermediate output.
While creating this sort of modularity requires a bit more setup than the straightforward single-flow approach, it comes with the following benefits:
-
You only need to figure out one piece of the flow at a time rather than getting every piece right
-
An error at a later stage of the process doesn’t require you to re-process earlier parts of the process
- e.g. If you run into an error when getting the list of makers, you don’t need to go through all the products again in the site — you would already have collected all of them in a spreadsheet
-
You automatically have a record of all the intermediate steps and data you’ve processed
- e.g. If you ever wanted to unfollow all the makers you followed this way, all you’d have to do is go through the spreadsheet containing the maker URLs and click “Unfollow”.
While the single-flow approach feels more intuitive (it’s generally how someone would think to do it manually without browser automation software), the multi-flow approach provides enough benefits that I think I want to encourage people to write their flows this way and provide support for it as a first-class paradigm.
At a high level, this is how the same ProductHunt automation would be accomplished with multiple flows:
- Flow #1 loops through today’s products and writes their URLs in a spreadsheet
- Flow #2 reads the spreadsheet from Flow #1, opens each product URL, loops through each maker of the product, and writes their URLs in a spreadsheet
- Flow #3 reads the spreadsheet from Flow #2, opens each maker URL, and clicks the follow button
This multi-flow approach would require changes to Browserflow Cloud so that once a flow finishes running, the next one in the sequence would start.
While there are commands to read spreadsheets, it’s not very user friendly because you need to get the spreadsheet using Get CSV Input, put the result in Loop List Items, and then get the cells of the spreadsheet using Run Script. Unless you have an example in front of you (or you’re the one who came up with all this), it’s pretty difficult to work with.
Here are the commands I’d like to create:
-
Loop Spreadsheet Rows
- Automatically populates variables named after the header row fields
-
Find Spreadsheet Row
- Allows you to check whether a row in the spreadsheet exists for the given field and value
-
Update Spreadsheet Row
- Allows you to add a field to an existing row (e.g. updating the “Status” field from “TODO” to “Done”)
Now for the hard part: Should I work on this now?
This doesn’t meet my criteria of “is this really necessary right now?” but it’d improve a common pattern enough that I think it’s worth prioritizing. But then again, this is how I feel about basically every feature which is why it’s been almost a year of me building this. I’m not even going to pretend like this is somehow different but hey, I get to call the shots so I’m going to give this a shot for a day and see where it goes.